Key Takeaways
- Data engineering best practices help create strong and secure pipelines that will help a business make decisions effectively.
- It is possible to ensure that the data will come to you properly with a correct definition of the requirements and ingestion strategy.
- Idempotence, automation of quality checks, transformation standardization, and incrementality are methods that increase the stability and performance of the pipeline.
- Pipeline orchestration, versioning, CI/CD pipeline, and data observability increase automation and monitoring of pipelines.
- Good security, governance, documentation, lineage, and life cycle management guarantee that no sensitive data is exposed while assuring good traceability of data at a reasonable cost.
- Choosing the right technology, avoiding frequent pitfalls, and tracking metrics like data freshness, number of pipeline failures, time to recover, and pipeline cost should happen during the development stage.
Data is only useful if people can trust it. But there are many instances where pipelines function "well" but actually produce duplicates, delays in reporting, and inaccurate numbers. These lead to faulty dashboards, unreliable AI models, and even skepticism regarding one's own analytics capabilities.
This lack of trust is getting bigger day by day. In the recent State of Analytics Engineering Report of dbt Labs for 2026, 83% of respondents mentioned trust in data as an organizational priority compared to 66% in the previous year. In order to integrate AI, mere speed in transferring data will not suffice anymore.
Good tools alone won't get you there. You need clear standards at every stage, from ingestion and testing to monitoring and governance.
In this article, we'll discuss 15 best practices in data engineering that will allow you to create pipelines that are both reliable and easy to maintain. For each of them, we'll tell you what it means, how to use it in your work, what pitfalls you should be aware of, and how to track its effectiveness.
What Are Data Engineering Best Practices?
The best data engineering practices are well-tested practices that can enable you to build a reliable data system. It helps teams provide accurate data while maintaining the efficiency of the pipeline.
Common practices include:
- Automating data quality checks.
- Using version control and automated testing.
- Processing only new or changed records when appropriate.
- Managing pipeline dependencies and failures.
- Checking the currency, performance, and cost-efficiency of data.
- Securing private data by limiting access to it and encrypting it.
For instance, a pipeline for loading customer transactions to a data warehouse needs to do more than just load records. It needs to check if all required fields are included, resolve duplicates, catch schema evolution, and notify engineers in case of failed loads.
The solution will differ depending on the workload. The daily reporting pipeline will have other requirements than a real-time fraud detection pipeline that needs low latency and fast recovery.
What Is Data Engineering about?
Data engineering includes all of the following components of the data lifecycle:
- Data ingestion: The process of data collection through databases, APIs, files, and events.
- Data storage: The process of organizing data in databases, warehouses, lakes, and lakehouses.
- Data transformation: The process of data cleansing and reformatting for business purposes.
- Workflow orchestration: Scheduling data jobs, managing dependencies, handling retries, and coordinating backfills and recovery.
- Data validation, governance, and security: Validation of records, data ownership, and access control.
- Monitoring and optimization: Detection of failures and enhancement of performance and cost savings.
An issue at any one point could affect the entire pipeline. For example, an issue with the data ingestion phase would cause the sales figures to be incomplete on the dashboard.
What Makes a Data Pipeline Reliable?
A robust data pipeline ensures that the data is right and delivered on time, and failures do not affect the result.
Key characteristics include:
- Accuracy: Data matches its origin and business logic.
- Completeness: The expected data is not quietly dropped.
- Freshness: The data will be available within the right time frame.
- Consistency: Repeatable results will be produced from multiple executions.
- Fault tolerance: Failures from temporary components will be allowed.
- Observability: The problems can be detected through logging, metrics, and alerts.
- Security: Secure handling of sensitive data will be applied.
- Recoverability: Failed jobs can be resubmitted without generating duplicates.
All of these should be established before designing the pipeline and establishing any performance requirements.
Data Engineering Best Practices VS DataOps
The best practices of data engineering involve creating data systems that are dependable. DataOps involves the use of automation and collaboration for developing, testing, deploying, and maintaining data pipelines.
| Aspect | Data engineering best practices | DataOps |
| Primary focus | Designing and operating reliable data systemsDesigning and operating reliable data systems | Improving the delivery and operation of data workflows |
| Typical activities | Data modeling, validation, pipeline design, security, and optimization | CI/CD, automated testing, deployment workflows, collaboration, and monitoring |
| Main objective | Deliver accurate, secure, and usable data | Make data delivery more consistent, repeatable, and efficient |
| Relationship | Provides technical principles and implementation standards | Applies operational and collaborative practices across the data lifecycle |
Both of these approaches complement each other. For instance, creation of the rules for data quality is a process of data engineering; automatic test execution on deployment is one of the elements of DataOps. Typically, both strategies allow the team to create better-designed, more efficient, manageable, and scalable pipelines.
Strengthen Your Data Infrastructure With Expert Engineering Support
Why Is It Important To Have Best Practices In Data Engineering?
Good data engineering practices will improve data quality, reliability of the pipeline, security, and performance of the pipeline. This allows organizations to manage their costs while scaling with the growing loads. Alternatively, it would not be easy for organizations to maintain their pipelines clean and error-free from errors that might affect the process of decision-making
1. Improve Data Quality and Reliability
Automated validation, schema validation, and reconciliation will assist in detecting missing records, duplicates, and discrepancies before affecting the process of analytics. Documentation and data ownership will be helpful here as well.
2. Increase Pipeline Reliability
Failure detection and handling via errors and retries, recovery, monitoring, and alerts will allow failure detection and pipeline operation recovery. The availability and freshness of the SLA of the data will make the reliability of the service measurable.
3. Increase Scalability and Performance
By increasing processing, partitioning, and parallel execution, query optimizations will help in handling more data. The right selection of techniques will guarantee performance and ease of implementation.
4. Lower Cost and Technical Debt
Resource monitoring, reuse of transformation logic, and efficient data processing will help decrease the cost of infrastructure and duplicated effort. Regular review of compute resource usage and data storage will be helpful here as well.
5. Strengthen Data Security and Governance
Data sensitive information will be safeguarded by means of least-privilege access control, encryption, secrets management, audit, and retention. The very same controls will ensure proper data governance and compliance with regulations.
6. Enhanced Analytics and ML Capabilities
Data models, data transformations, and data quality/lineage will enable machine learning and analytics to utilize trusted data sources. Some additional controls could be required for artificial intelligence projects in terms of quality of training data sets, feature standardization, and data drift.
Best Practices for Data Engineering: 15 Tips to Improve Data Pipelines
Efficient data pipeline design always begins with establishing requirements and architecture. After that, it is time to optimize data quality, automation, security, and cost reduction.
Here are 15 tips covering all the main stages of data engineering that will help you improve your data pipelines.
1. Clearly Define Data Requirements and SLAs
Before designing a data pipeline, it is necessary to identify what the pipeline has to provide and how quickly. Otherwise, it might run successfully, but the output data can be incomplete, or the deadlines for your business could be missed.
Identify which parties would consume the data, how often the data should be refreshed, and how accurate the data should be, and turn this information into specific metrics.
How to Define Data Pipeline Requirements
There are 5 areas to focus on:
- Data consumers: Identify all dashboards, applications, reports, and AI workflows that rely on the data.
- Data freshness: Define when the data should be available. The data used by a real-time application should be available in seconds, while a weekly report would need a daily update schedule.
- Data quality: Define rules for completeness, validity, consistency, and uniqueness.
- Availability and recovery: Decide how quickly failures must be resolved and whether historical data needs to be reprocessed.
- Ownership and dependencies: Assign responsibility for the pipeline and document the systems that supply or consume its data.
These requirements give engineers a clear basis for choosing an architecture, setting priorities, and measuring success.
Understand SLAs, SLOs, and SLIs
Service-level agreements (SLAs), service-level objectives (SLOs), and service-level indicators (SLIs) help teams translate operational expectations into measurable targets.
| Term | Meaning | Data engineering example |
| SLA | An agreement defining service expectations and, where applicable, consequences for missing them | A contractual commitment to deliver a customer report by 8:00 AM |
| SLO | A measurable target for service performance or reliability | 99% of scheduled daily datasets are available by 7:00 AM over a rolling 30-day period |
| SLI | A metric used to evaluate actual performance against an objective | Percentage of scheduled days when validated datasets are available by 7:00 AM |
Choose metrics that reflect downstream users' needs, not just whether a pipeline runs successfully. A job may complete without errors but still deliver incomplete data or miss its freshness deadline.
For the example above, calculate the SLI by dividing the number of scheduled days when the validated dataset is available by 7:00 AM by the total number of scheduled days in the 30-day window. Count each scheduled day that misses the deadline as a failure, including days when the pipeline fails or produces data that does not pass required quality checks. The resulting percentage shows whether the pipeline meets its 99% SLO.
Example: Setting Requirements for a Sales Pipeline
Imagine an e-commerce company that needs daily sales data for its revenue dashboard.
| Requirement | Example target | How to measure it |
| Data freshness | Dashboard dataset available by 7:00 AM | Dataset publication timestamp |
| Completeness | All expected source files or partitions are processed | Expected-versus-processed record or partition counts |
| Uniqueness | No duplicate transaction IDs in the curated dataset | Duplicate-key validation |
| Reliability | 99% of scheduled runs are complete within the agreed window | Successful on-time runs divided by scheduled runs |
| Recovery | Restore service within a defined recovery window | Time from incident detection to service restoration |
These are illustrative targets, not universal benchmarks. Choose targets based on business impact, processing costs, and the consequences of missing or incorrect data.
Best practice: Document requirements before implementation, assign an owner to each critical dataset, and monitor the agreed targets in production.
2. Build Scalable Data Architectures
A scalable data architecture allows data pipelines to handle growing data volumes, more users, and changing business requirements without requiring a complete redesign. Choosing the right architecture early helps teams maintain performance, control costs, and simplify pipeline maintenance.
The goal is not to build the most complex system. It is to choose an architecture that meets current needs while leaving room for future growth.
How to Build a Scalable Data Architecture
- Choose the right storage platform: Use a data warehouse for structured analytics, a data lake for diverse data formats, or a lakehouse when you need capabilities from both approaches.
- Separate ingestion, storage, and transformation: Keep pipeline components modular so teams can update or scale individual stages without disrupting the entire workflow.
- Design for changing workloads: Consider partitioning, parallel processing, and distributed computing when data volume or processing demands justify them.
- Plan for failure and recovery: Identify critical dependencies and establish backup, recovery, and retry mechanisms appropriate to the workload.
- Avoid unnecessary dependencies on specific tools: Use documented interfaces, standard data formats, and well-defined transformation contracts where practical.
Data Warehouse vs. Data Lake vs. Lakehouse
| Architecture | Best suited for | Key consideration |
| Data warehouse | Structured data, reporting, and business intelligence | Strong support for governed analytical queries |
| Data lake | Large volumes of structured, semi-structured, and unstructured data | Requires effective metadata and data governance |
| Data lakehouse | Analytics across diverse datasets with warehouse-like management capabilities | Requires careful platform design and operational management |
Example: Scaling a Sales Analytics Pipeline
Suppose a business initially processes a few thousand sales records daily but eventually handles millions of transactions. A tightly coupled pipeline may become slow and difficult to maintain.
A modular architecture can help the team scale ingestion and transformation independently, partition large datasets for efficient queries, and process new records without repeatedly reprocessing historical data.
Best practice: Build an architecture around actual data requirements, expected growth, and operational constraints. A modular, well-governed design is generally easier to scale and maintain than an unnecessarily complex system.
3. Choose the Right Data Ingestion Strategy
Data ingestion is the process of moving data from source systems into a data warehouse, data lake, or other destination for processing and analysis.
Choosing the right ingestion strategy helps data engineering teams maintain data freshness, reduce processing costs, and build reliable pipelines. The best approach depends on how much data you process, how frequently it changes, and how quickly users need access to it.
How to Implement It
Identify your data sources. Determine whether data comes from databases, APIs, files, or event streams. Check which extraction methods each source supports.
- Define data freshness requirements. Decide how quickly data must become available. Daily reports may work with batch processing, while time-sensitive applications may require streaming.
- Choose the appropriate ingestion method. Use batch processing for scheduled loads, incremental ingestion for capturing changes, and streaming for continuous data delivery.
- Handle failures and duplicate records. Implement retries, checkpoints, and validation so temporary failures do not result in missing or duplicated data.
- Track ingestion progress. Record ingestion timestamps, source identifiers, and processing status to make troubleshooting and recovery easier.
Common Data Ingestion Strategies
- Batch ingestion
- Incremental ingestion
- Change data capture (CDC)
- Streaming ingestion
- API-based ingestion
These approaches can work together. For example, a company might use CDC for its transactional database, API-based ingestion for its CRM, and batch processing for historical sales files.
Example: Ingesting Data for Sales Analytics
Consider an e-commerce company that collects order data from a database, customer information from a CRM, and website activity from an event stream.
The team could use CDC to capture order changes, incremental API extraction to retrieve updated customer records, and streaming to process website events.
This approach avoids repeatedly loading unchanged data while making information available at the speed each business process requires.
For instance, the company might set a 15-minute freshness target for order analytics and a one-minute target for website activity. These are illustrative targets; actual requirements depend on business needs and system capabilities.
Best practice: Choose an ingestion strategy based on data volume, freshness requirements, and source capabilities. Reliable ingestion should capture changes efficiently, handle failures gracefully, and provide enough visibility to detect and resolve problems.
4. Design Idempotent and Fault-Tolerant Pipelines
Data pipelines can fail because of network interruptions, source system outages, or processing errors. When a failed job is retried, it should not create duplicate records or corrupt previously processed data.
Two important data engineering best practices help prevent these problems: idempotency and fault tolerance.
Idempotency means running the same operation multiple times produces the same final result as running it once.
Fault tolerance means a pipeline can handle failures and recover without losing data or leaving datasets in an inconsistent state.
Together, these principles make data pipelines more reliable and easier to maintain.
How to Implement It
- Use stable record identifiers. Assign unique keys to records so the pipeline can identify duplicates and apply updates correctly.
- Make retries safe. Use idempotent writes, upserts, or deterministic transformations so retrying a failed job does not create duplicate results.
- Track processing progress. Maintain checkpoints or source offsets to identify which records have already been processed and where processing should resume.
- Handle failures systematically. Use controlled retries with exponential backoff for temporary errors. Send repeatedly failing records to a dead-letter queue or quarantine area for investigation.
- Validate results before publishing them. Check record counts, required fields, and other relevant conditions before making processed data available to downstream systems.
Example: Preventing Duplicate Orders
Consider an e-commerce company that processes incoming order events. A pipeline writes 1,000 orders to its data warehouse, but the job fails before reporting successful completion.
When the job runs again, it may process the same orders.
Without proper safeguards, the warehouse could contain duplicate orders, inflating revenue reports and misleading business decisions.
To prevent this, the pipeline can use a unique order ID and an upsert operation. When an order already exists, the pipeline updates the existing record instead of inserting another copy.
The team should also track processing progress and validate the final order count.
Important: Idempotency does not automatically prevent every duplicate. For example, an upsert based on order ID will not resolve duplicates if the source generates different IDs for the same business event. Reliable deduplication depends on choosing the correct business key and defining how conflicting updates are handled.
Best practice: Design pipelines so that retries are safe, processing progress is recoverable, and failures do not leave data in an inconsistent state. Use stable identifiers, idempotent writes, checkpoints, and validation to improve pipeline reliability.
5. Implement Automated Data Quality Checks
Reliable data pipelines must do more than move data successfully. They must also ensure that the data is accurate, complete, consistent, and suitable for its intended use.
Without data quality checks, missing values, duplicate records, invalid formats, and unexpected changes can reach dashboards, reports, and machine learning systems. These problems can undermine trust in data and lead to poor business decisions.
Automated data quality checks help detect these issues early, ideally before unreliable data reaches downstream users.
How to Implement It
- Define quality rules for critical datasets. Identify the conditions that data must satisfy, such as required fields, valid ranges, unique identifiers, and acceptable record counts.
- Validate data at key pipeline stages. Run checks after ingestion, during transformation, and before publishing datasets for analytics. Focus on the stages where errors are most likely to occur.
- Automate recurring checks. Use data testing frameworks or built-in validation features to run checks whenever pipelines execute or datasets change.
- Set thresholds for failures. Decide which issues should stop a pipeline and which should generate a warning. Missing primary keys may require stopping publication, while a small variation in optional fields may only need investigation.
- Monitor recurring quality problems. Track failed checks over time to identify patterns, investigate root causes, and prevent the same issues from recurring.
Example: Improving Data Quality in Sales Reporting
Suppose a retail company loads order data into its analytics warehouse. A source system change causes some records to arrive without customer IDs, while another process introduces duplicate orders.
Without validation, these records could distort sales reports and customer analyses. The team can introduce automated tests to verify that:
Every order has a valid order ID.
- Order IDs are unique within the intended dataset.
- Order amounts satisfy the defined business rules.
- Customer IDs reference existing customer records.
- Daily order volumes remain within an expected range.
If duplicate orders are detected, the pipeline can quarantine affected records or stop publication until the issue is resolved. Missing customer IDs may be handled differently depending on whether they are essential to the reporting use case. This approach helps catch problems before they affect business users.
Best practice: Automate data quality checks throughout the pipeline, prioritizing critical business rules and high-impact datasets. Combine validation with monitoring, clear failure thresholds, and root-cause analysis to make data more trustworthy.
6. Standardize Data Modeling and Transformations
Data modeling and transformation determine how raw data becomes useful for reporting, analytics, and business decisions. Without consistent standards, different teams may calculate the same metric differently, create duplicate logic, or produce datasets that are difficult to maintain.
Standardizing these processes helps teams build consistent, understandable, and reusable data assets. A good starting point is to define how data is structured, how business metrics are calculated, and how transformations are tested before their results reach downstream systems.
How to Implement It
- Define consistent naming conventions. Use clear, predictable names for tables, columns, and models. For example, standardize whether timestamps use names such as created_at or order_created_at.
- Establish a common data model. Organize data into appropriate structures, such as fact and dimension tables for analytical workloads. Define relationships and business keys consistently across datasets.
- Centralize business logic. Avoid implementing the same calculation separately in multiple dashboards or pipelines. Maintain shared definitions for metrics such as revenue, customer retention, and order count.
- Separate raw data from transformed data. Preserve source data where appropriate and create structured transformation layers. This makes it easier to trace results back to their origins and troubleshoot errors.
- Test and document transformations. Validate calculations, relationships, and expected outputs. Document important business rules so analysts and engineers understand how each dataset is produced.
Example: Standardizing Revenue Calculations
Imagine two data analytics teams reporting revenue for the same e-commerce business. One calculates revenue using completed orders, while the other includes cancelled orders and refunds.
Both dashboards may process their data successfully, but their results will differ.
The data engineering team can solve this problem by defining a shared revenue calculation, documenting how cancellations and refunds are treated, and implementing the logic in a reusable transformation model.
Both teams can then use the same trusted dataset instead of maintaining separate calculations.
Best practice: Standardize data models, naming conventions, and business logic so teams can work with consistent, reusable datasets. Well-tested transformations reduce duplication, simplify maintenance, and improve trust in analytical results.
7. Use Incremental Processing Where Appropriate
Processing an entire dataset every time a pipeline runs can waste compute resources and increase execution time, especially as data volumes grow.
Incremental processing addresses this problem by processing only new or changed records since the previous successful run. It can make pipelines faster and more cost-efficient while helping large datasets scale.
However, incremental processing is not suitable for every workload. Full refreshes may still be necessary for small datasets, complete snapshots, or transformations that depend on the entire dataset.
How to Implement It
- Identify what changes between runs. Determine whether the source provides timestamps, change logs, CDC events, or another reliable way to identify new and updated records.
- Track processing progress. Store a checkpoint or watermark that identifies the last successfully processed batch or change. Advance it only after the relevant data has been processed successfully.
- Handle updates and deletions. Ensure the pipeline captures changes to existing records and removes records when required. CDC can help when source systems expose these changes.
- Make incremental writes reliable. Use appropriate merge or upsert operations and stable business keys to avoid duplicate records when batches are retried.
- Validate incremental results. Compare record counts, important metrics, and selected records against expected results. Periodic reconciliation or full refreshes can help identify missed changes.
Example: Incremental Processing for Sales Data
Suppose an e-commerce company stores millions of historical orders but receives only a small number of new or updated orders between scheduled runs. Instead of reloading the entire order table every hour, the team can process records that have changed since the previous run.
For example, the pipeline could use CDC to capture new orders, changes to existing orders, and cancellations. It would then merge those changes into the analytical table using the order ID. This reduces unnecessary processing while keeping the analytical dataset updated.
Important: A simple timestamp filter can miss records when timestamps are unreliable, updates arrive late, or multiple records share the same timestamp. Use a reliable change-tracking mechanism and account for late-arriving data.
Best practice: Use incremental processing when it reduces unnecessary work without compromising correctness. Reliable change tracking, safe writes, and periodic reconciliation help keep datasets accurate as data volumes grow.
8. Automate Orchestration and Dependency Management
Data pipelines often consist of multiple tasks that must run in the correct order. For example, data must be ingested before it can be transformed, and transformations must finish before a reporting table is refreshed.
Data orchestration coordinates these tasks, manages their dependencies, and handles execution schedules. Without proper orchestration, teams may rely on manual triggers, duplicate scheduling logic, or struggle to recover when an upstream task fails. Automating orchestration makes workflows easier to manage, monitor, and scale.
How to Implement It
- Define task dependencies. Map which tasks must finish before others begin. Ensure downstream jobs do not process incomplete upstream data.
- Set appropriate schedules and triggers. Run jobs at intervals that match business requirements, or trigger them when new data becomes available.
- Configure retries and failure handling. Retry temporary failures, alert the responsible team when necessary, and prevent failed upstream tasks from silently producing unreliable downstream results.
- Make workflows restartable. Design tasks so they can resume safely after interruptions without unnecessarily repeating completed work or duplicating records.
- Monitor workflow execution. Track task duration, failures, missed schedules, and dependency delays to identify bottlenecks and improve reliability.
Example: Automating a Sales Reporting Pipeline
Consider a company that refreshes its sales dashboard every morning. The workflow includes three tasks:
- Ingest the latest order data.
- Transform and validate the order records.
- Refresh the reporting tables.
An orchestration tool ensures that the transformation task starts only after ingestion completes successfully. The reporting tables are refreshed only after transformation and validation succeed.
If ingestion fails, the workflow can retry the task and notify the responsible engineer if recovery is unsuccessful. This prevents the dashboard from being refreshed with incomplete data.
Tools such as Apache Airflow, Dagster, and Prefect can help teams define, schedule, and monitor these workflows.
Best practice: Automate pipeline scheduling, dependencies, retries, and failure handling through a suitable orchestration system. Well-designed workflows reduce manual intervention and help ensure that downstream datasets are updated only when their dependencies are ready.
9. Adopt Version Control and CI/CD
Data pipelines evolve as business requirements change, source systems introduce new fields, and transformation logic becomes more complex. Without version control and controlled deployment processes, even a small change can introduce errors that affect downstream reports and applications.
Version control tracks changes to pipeline code and configuration, while continuous integration and continuous delivery or deployment (CI/CD) automate testing and the release of those changes.
Together, they help data engineering teams collaborate more effectively, identify errors earlier, and roll back problematic changes when necessary.
How to Implement It
- Store pipeline code in version control. Use Git or a similar system to track changes to SQL transformations, orchestration workflows, configuration files, and infrastructure definitions.
- Use branches and code reviews. Have engineers review changes before merging them into the main branch. This helps catch logic errors and makes changes easier to understand.
- Automate testing before deployment. Run unit tests, transformation tests, data quality checks, and relevant integration tests to identify problems before code reaches production.
- Separate development, testing, and production environments. Validate changes against representative data in a non-production environment before releasing them to live pipelines.
- Plan for rollback and recovery. Keep track of deployed versions and define how to revert code or restore affected datasets if a release causes problems.
Example: Safely Updating a Data Transformation
Suppose a data engineer changes the SQL logic used to calculate monthly revenue.
Before the change reaches production, a CI/CD workflow can run automated tests against sample data and verify that refunds, cancellations, and other business rules are handled correctly.
After the tests pass and the change receives approval, the updated transformation can be deployed to production. If the new logic produces incorrect results, the team can revert the code to a previous version and follow its recovery procedure to correct any affected data.
Best practice: Use version control, code reviews, automated testing, and controlled deployments to make pipeline changes safer and more traceable. Treat code rollback and data recovery as separate concerns when designing your release process.
10. Monitor Pipelines with Observability and Alerting
A data pipeline can fail without anyone noticing immediately. It may stop processing records, deliver stale data, or complete successfully while producing incorrect results.
Monitoring and observability help data engineering teams detect these problems, understand their causes, and resolve them before they significantly affect downstream users.
Monitoring tracks predefined metrics and alerts, while observability helps engineers investigate unexpected behavior using metrics, logs, traces, and other diagnostic information.
How to Implement It
- Track pipeline health. Monitor execution status, processing duration, record counts, and failure rates to identify unusual behavior.
- Measure data freshness. Track when data was last updated and compare it with the freshness requirements established for each dataset.
- Configure meaningful alerts. Notify the responsible team when critical pipelines fail, freshness targets are missed, or data quality checks detect serious issues.
- Centralize logs and diagnostic information. Capture error messages, job identifiers, processing checkpoints, and relevant source details to simplify troubleshooting.
- Review recurring problems. Analyze failures, processing delays, and resource bottlenecks to identify opportunities for improvement.
Example: Detecting Stale Sales Data
Suppose a retailer expects its sales dashboard to refresh every 15 minutes. An upstream database becomes unavailable, preventing the ingestion pipeline from completing.
Without freshness monitoring, the dashboard might continue displaying old figures without warning users.
A monitoring system can detect that the dataset has exceeded its freshness target and alert the responsible engineer. The team can then investigate the source failure, restore ingestion, and verify that the missing data has been processed.
The 15-minute target is illustrative; actual thresholds should reflect business requirements.
Best practice: Monitor both pipeline execution and the condition of the data it produces. Meaningful alerts, useful diagnostic information, and clear ownership help teams detect issues earlier and reduce recovery time.
11. Apply Security, Privacy, and Access Controls
Data pipelines often process sensitive information, including customer details, financial records, and business transactions. Without appropriate security controls, this data can be exposed to unauthorized users or systems.
Security should be built into every stage of the data lifecycle, from ingestion and processing to storage and sharing.
How to Implement It
- Apply least-privilege access. Give users and pipeline services only the permissions they need to perform their tasks.
- Encrypt data in transit and at rest. Use appropriate encryption mechanisms to protect information as it moves between systems and while it is stored.
- Manage credentials securely. Store passwords, API keys, and other secrets in a secrets manager rather than hardcoding them in pipeline code.
- Protect sensitive fields. Use masking, tokenization, or pseudonymization where appropriate, particularly in development and testing environments.
- Audit access and retention. Record relevant access activity and define how long sensitive data should be retained before it is deleted or archived.
Example: Protecting Customer Data
Suppose an e-commerce company uses customer records for sales analytics. Analysts need customer segments and purchase histories, but they may not need direct access to email addresses or phone numbers.
The data engineering team can restrict access to raw customer data and publish a curated analytical dataset with unnecessary personal identifiers removed or masked.
This allows analysts to perform their work while reducing unnecessary exposure of sensitive information.
Best practice: Apply least-privilege access, secure credential management, encryption, and appropriate data protection controls throughout the pipeline. Security requirements should reflect the sensitivity of the data and applicable legal obligations.
12. Maintain Metadata, Documentation, and Data Lineage
Data becomes difficult to manage when teams do not know where it comes from, what it means, or how it changes as it moves through a pipeline.
Metadata describes data assets and their properties. Documentation explains how datasets and pipelines work, while data lineage shows how data flows from source systems through transformations to its final destination.
Together, these practices make data easier to discover, understand, troubleshoot, and govern.
How to Implement It
- Document important datasets. Record their purpose, owners, schemas, update frequency, and intended use.
- Track data lineage. Capture relationships between source tables, transformation jobs, and downstream datasets.
- Maintain a data catalog. Help users discover available datasets and understand their definitions, quality, and access requirements.
- Assign clear ownership. Identify the team or individual responsible for maintaining each critical dataset.
- Keep documentation current. Update metadata and lineage when schemas, transformations, or dependencies change.
Example: Tracing an Incorrect Revenue Figure
Suppose a finance team discovers that monthly revenue in its dashboard does not match the transactional system.
With data lineage, engineers can trace the dashboard metric back through its transformation models to the original order tables. They can then identify whether the discrepancy originated in ingestion, transformation logic, or the source data itself.
Without this visibility, engineers may need to investigate several disconnected systems manually.
Best practice: Maintain searchable metadata, useful documentation, and traceable data lineage. These practices reduce investigation time and help teams understand the origin, meaning, and downstream impact of their data.
13. Optimize Storage, Compute, and Data Lifecycle Management
As data volumes grow, inefficient storage and processing can increase infrastructure costs and slow down pipelines. Retaining unnecessary data or repeatedly processing unchanged records can also make a data platform harder to maintain.
Effective optimization balances performance, cost, data availability, and retention requirements.
How to Implement It
- Choose appropriate storage formats. Use formats such as Parquet or ORC for analytical workloads when their columnar structure and compression provide benefits.
- Optimize query and processing patterns. Filter unnecessary records early, select only required columns, and avoid repeatedly processing unchanged data.
- Manage partitioning and file sizes. Partition large datasets according to common query patterns, and compact small files when excessive file counts affect performance.
- Apply lifecycle policies. Define when data should remain readily accessible, move to lower-cost storage, or be deleted according to business and legal requirements.
- Monitor cost and performance together. Track compute consumption, storage growth, query performance, and workload frequency before making optimization decisions.
Example: Reducing Data Warehouse Costs
Suppose a retailer reloads its entire historical sales dataset every night, even though only the latest day's transactions have changed.
The engineering team can introduce incremental processing and optimize the analytical tables for common reporting queries. It can also review unused historical datasets and apply appropriate retention or archival policies.
The result may be lower processing costs and faster reporting, although actual savings depend on the workload, storage architecture, and implementation.
Best practice: Optimize data processing and storage based on actual workload patterns. Combine efficient formats, appropriate partitioning, incremental processing, and lifecycle policies to balance performance, cost, and long-term data management.
14. Establish Incident Response and Recovery Procedures
Even well-designed data pipelines can fail because of source outages, infrastructure problems, software changes, or unexpected data issues. What matters is how quickly teams detect these incidents, restore reliable processing, and prevent the same problems from recurring.
A defined incident response process helps teams recover systematically instead of relying on improvised fixes.
How to Implement It
- Define incident severity levels. Prioritize incidents according to their impact on critical datasets, business operations, and downstream consumers.
- Assign ownership and escalation paths. Establish who investigates each incident and when additional teams should be involved.
- Document recovery procedures. Create runbooks for common failures, including source outages, failed transformations, and corrupted outputs.
- Plan for replay and backfills. Define how missing records or historical periods can be reprocessed safely after an interruption.
- Review incidents after recovery. Identify root causes and implement corrective actions to reduce the likelihood of recurrence.
Example: Recovering from a Failed Ingestion Job
Suppose a source database becomes unavailable for two hours, preventing the pipeline from loading new transactions.
The monitoring system alerts the responsible engineer, who investigates the source failure. Once the database becomes available, the team resumes ingestion from a reliable checkpoint and processes the missing changes.
Before restoring the downstream dashboard, the team verifies data completeness and confirms that replayed records have not created duplicates.
This recovery process helps restore trustworthy data rather than simply marking the failed job as successful.
Best practice: Prepare for pipeline failures with clear ownership, documented recovery procedures, reliable checkpoints, and tested restoration mechanisms. Measure recovery performance against business-defined service-level objectives (SLOs).
15. Prepare Reliable Datasets for Analytics and AI
Data engineering supports more than traditional reporting. Data analytics consulting teams, machine learning engineers, and AI developers all depend on data that is reliable, well-documented, and appropriate for its intended use.
A dataset that works for a dashboard may not automatically be suitable for model training or an AI-powered application. Different use cases require different levels of detail, freshness, consistency, and validation.
Preparing data for downstream consumption helps organizations use their data more effectively while reducing avoidable errors.
How to Implement It
- Define the intended use. Understand whether a dataset supports reporting, machine learning, retrieval-augmented generation (RAG), or another application.
- Standardize and validate the data. Resolve inconsistent formats, handle missing values appropriately, and validate important business rules.
- Preserve useful context. Maintain timestamps, source references, business definitions, and other metadata needed to interpret records correctly.
- Manage historical data carefully. For machine learning, prevent data leakage by ensuring that training features reflect information available at the relevant prediction time.
- Control access and refreshes. Ensure downstream systems use authorized datasets and that updates are reflected according to their freshness requirements.
Example: Preparing Data for an AI Assistant
Suppose a company wants to build an AI chatbot assistant that answers questions about product documentation and internal policies.
The data engineering team must collect relevant documents, remove or restrict sensitive information, standardize metadata, and ensure that the content can be retrieved efficiently.
The team should also track document versions and refresh indexed content when the authoritative source changes.
This helps the assistant retrieve relevant, current information. However, reliable data preparation alone does not guarantee accurate AI responses; retrieval quality, model behavior, and evaluation also matter.
Best practice: Prepare datasets according to the needs of their downstream consumers. Reliable, validated, well-documented data provides a stronger foundation for analytics, machine learning, and AI applications.
Make Your Data AI-Ready With Scalable Data Engineering Solutions
Data Engineering Best Practices Checklist
Use this checklist to evaluate whether your data pipelines are reliable, scalable, secure, and ready for production. It can serve as a starting point for architecture reviews, deployment approvals, and periodic data platform audits.
Data Engineering Implementation Review
Requirements and architecture
- Business requirements, data consumers, and dataset owners are documented.
- Architecture and ingestion methods match data volume, freshness, and latency requirements.
- Pipeline components are modular, maintainable, and version-controlled.
Data quality and processing
- Automated quality checks cover critical datasets and business rules.
- Retries, reruns, and backfills are safe and do not introduce unintended duplicates.
- Schema changes are detected, tested, and communicated to downstream consumers.
Orchestration and deployment
- Task dependencies, timeouts, and failure-handling rules are configured.
- CI/CD workflows include automated tests and validation before production deployment.
Security and governance
- Access controls follow the principle of least privilege.
- Sensitive data is protected through appropriate encryption, masking, and retention policies.
- Data lineage, ownership, and operational documentation are available for critical datasets.
Monitoring and operations
- Pipeline failures, data freshness, processing volumes, and quality issues are monitored.
- Performance and processing costs are reviewed regularly.
- Backup, recovery, and incident response procedures are documented and tested.
How to use the checklist: Prioritize controls according to business criticality, regulatory obligations, data sensitivity, and workload requirements. A financial reporting pipeline may require stricter reconciliation and recovery controls than a low-risk internal dashboard. Focus first on the gaps with the greatest potential impact rather than implementing every control with equal urgency.
Data Engineering Best Practices by Pipeline Stage
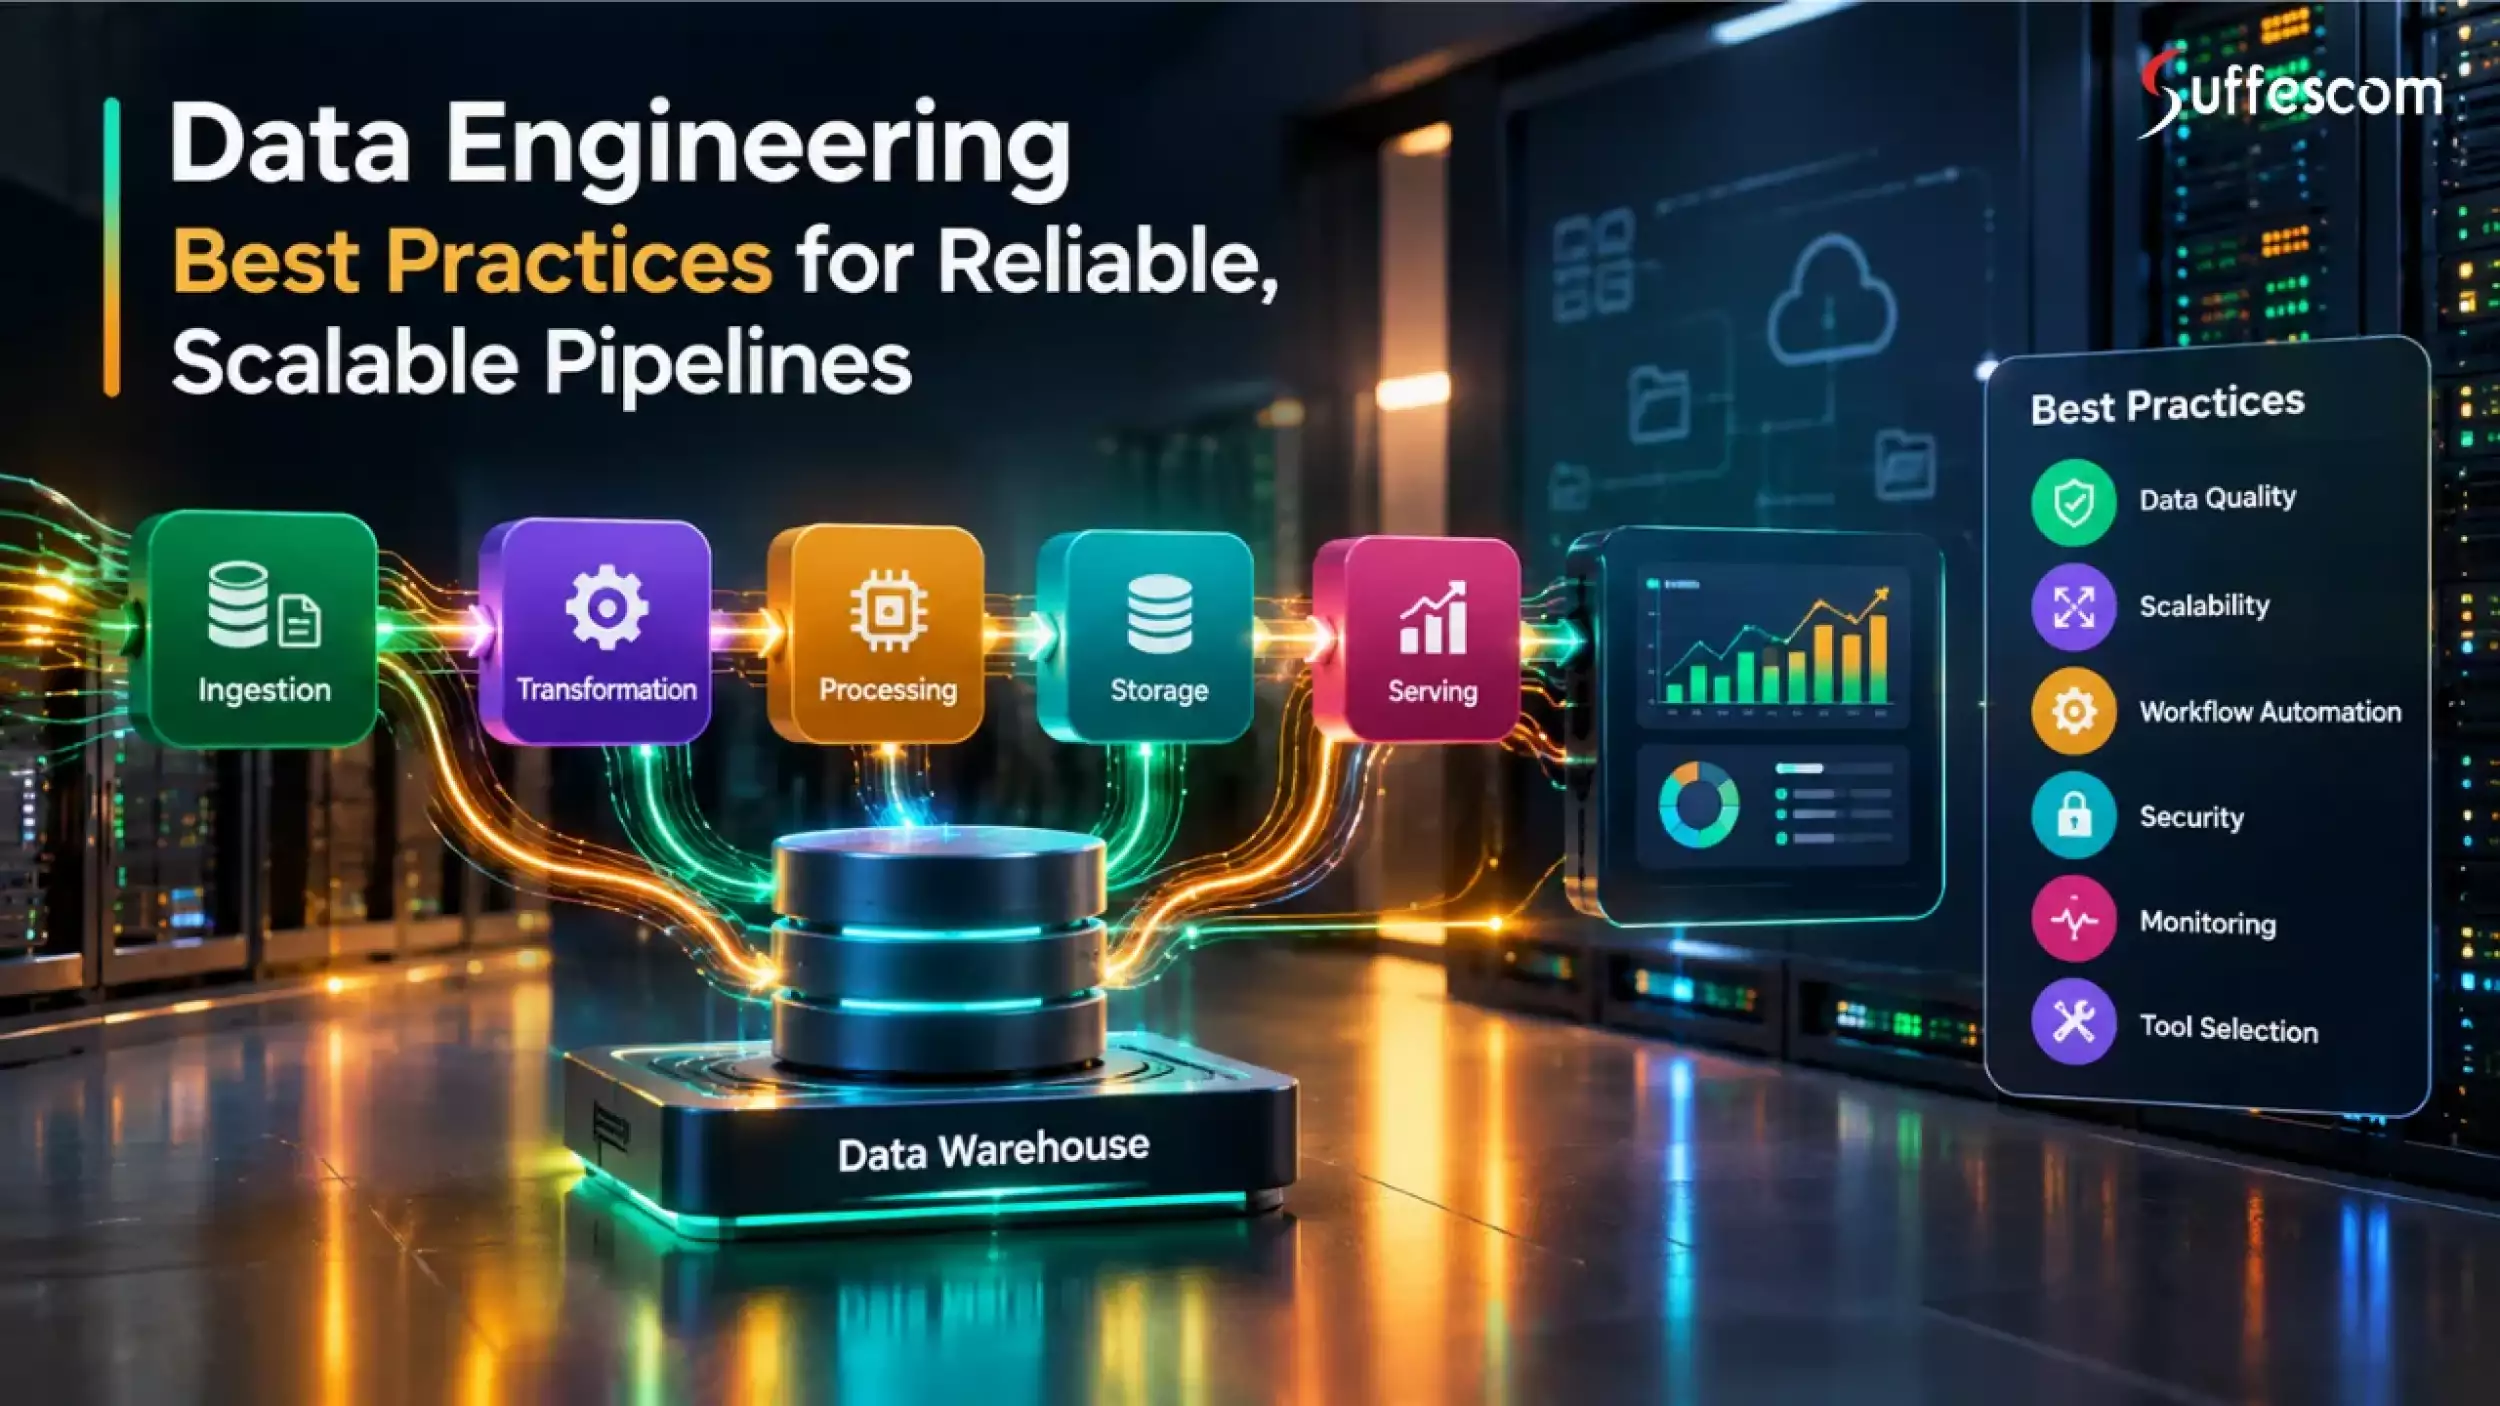
Data engineering best practices are most effective when they work together across the entire data lifecycle. Organizing them by pipeline stage helps teams understand where each practice applies and identify gaps between ingestion, transformation, storage, and delivery.
| Pipeline stage | Primary practices | Main objective |
| Source discovery | Requirements, ownership, data contracts | Understand source data, business rules, and consumer needs |
| Ingestion | Validation, incremental loads, CDC, safe retries | Capture data completely and efficiently |
| Storage | Security, partitioning, retention, lifecycle management | Store and manage data safely and cost-effectively |
| Transformation | Modular design, standardized models, testing, version control | Produce consistent, reusable datasets |
| Orchestration | Dependency management, scheduling, retries, recovery | Execute workflows in the correct order |
| Serving | Freshness checks, access controls, documentation | Deliver trusted data to analytics and applications |
| Operations | Observability, incident response, cost monitoring, disaster recovery | Maintain reliability and improve performance over time |
Example: Following an Order Through a Data Pipeline
Consider an e-commerce company that needs reliable order data for sales reporting.
- Define requirements: Establish which order fields are required, who owns the data, and how quickly updates must reach the warehouse.
- Ingest the data: Capture new orders and changes through batch ingestion, incremental extraction, or CDC, depending on source capabilities.
- Validate and store: Check required fields and record identifiers, then store the data securely with ingestion metadata.
- Transform and test: Apply consistent business rules, calculate analytical metrics, and test the resulting datasets.
- Publish the results: Make validated order data available to reporting tables with documented definitions and appropriate access controls.
- Monitor and recover: Track freshness, failures, and processing costs. If ingestion fails, recover from a reliable checkpoint and validate the reprocessed data before publishing it.
How to Choose the Right Data Engineering Tools
The right data engineering tools depend on your workload, existing infrastructure, reliability requirements, and team's operational capabilities. Choosing tools based on popularity alone can introduce unnecessary complexity and cost.
Start by identifying what the pipeline must accomplish. Then select tools that meet those requirements and integrate effectively with the rest of your data platform.
Consider these factors when comparing technologies.
- Data volume and latency: Determine whether the workload processes gigabytes or petabytes, and whether data must be available in seconds, minutes, or hours.
- Integration and compatibility: Check support for your databases, APIs, cloud platforms, file formats, and downstream applications.
- Scalability and reliability: Evaluate workload scaling, failure recovery, retry mechanisms, and support for peak processing volumes.
- Security and governance: Assess authentication, access controls, encryption, audit logs, and relevant compliance capabilities.
- Operational complexity: Consider deployment, upgrades, monitoring, troubleshooting, and the skills needed to maintain the platform.
- Total cost of ownership: Include infrastructure, licensing, storage, data transfer, support, and engineering time.
For example, a small analytics team running scheduled SQL transformations may not need a distributed streaming platform. A business processing continuous transactions with strict latency requirements may need more specialized ingestion and stream-processing capabilities.
The goal is to meet the workload's requirements without creating unnecessary operational overhead.
Open-Source vs. Managed Data Engineering Tools
Data engineering tools generally fall into two deployment models: open-source software that your team operates or managed services that outsource some infrastructure responsibilities to a provider.
Open-source tools
- Usually requires more direct operational responsibility
- Often offers extensive configuration and deployment flexibility
- Infrastructure, maintenance, and engineering time contribute to cost
- Depends on architecture and operational configuration
- Your team typically handles upgrades and compatibility
- Teams that need flexibility and have operational expertise
Managed tools
- The provider manages some or most of the underlying infrastructure
- Depends on the service's supported features
- Subscription or usage charges, plus any additional infrastructure costs
- May include built-in scaling features
- The provider handles supported service maintenance
- Teams that want to reduce infrastructure management
Neither approach is universally better. Open-source software can provide greater control, but operating it reliably requires engineering effort. Managed services can reduce that burden but introduce provider dependencies, pricing considerations, and possible platform limitations.
Evaluate the complete operating model rather than comparing software licensing costs alone.
How to Match Tools to Your Pipeline Requirements
Different tools solve different parts of the data engineering lifecycle. The following examples illustrate common categories and their roles.
| Tool category | Examples | When to consider it |
| Workflow orchestration | Apache Airflow, Dagster, Prefect | Coordinating scheduled jobs, dependencies, and retries |
| Data ingestion and CDC | Airbyte, Debezium | Connecting source systems and capturing data changes |
| Stream processing | Apache Flink, Kafka Streams | Processing continuous event streams |
| Distributed data processing | Apache Spark | Processing large datasets across distributed compute resources |
| Data transformation | dbt | Managing SQL-based analytical models and transformation tests |
| Analytical storage | Snowflake, Google BigQuery, Amazon Redshift | Storing and querying analytical datasets |
| Data quality | Great Expectations, Soda, dbt tests | Validating records, business rules, and dataset expectations |
| Observability | OpenTelemetry-based instrumentation and platform-native monitoring | Tracking execution behavior, performance, and failures |
These tools are modern rather than interchangeable. For example, Debezium can capture database changes, Kafka can transport events, Flink can process streams, and an analytical warehouse can store the resulting datasets.
A production architecture may combine several categories, but it does not need a separate tool for every possible function.
A practical selection process:
- Document the workload's volume, latency, reliability, and security requirements.
- Identify the capabilities already available in your cloud or data platform.
- Shortlist tools that meet the essential requirements.
- Test them against representative data volumes, failure scenarios, and integration needs.
- Compare operational effort and total cost before committing to the architecture.
Choose the simplest toolset that meets your requirements today while allowing reasonable growth. Add specialized technologies when the workload justifies their additional complexity.
Common Data Engineering Mistakes to Avoid
Even well-designed data platforms can become unreliable when teams overlook fundamental engineering practices. Common mistakes include processing data inefficiently, neglecting quality checks, and treating pipeline failures as isolated technical problems.
Understanding these issues helps teams prevent recurring failures and maintain trustworthy data.
- Loading entire datasets unnecessarily: Processing all historical data during every run increases execution time and resource costs. Use incremental processing when appropriate.
- Ignoring data quality: Missing, duplicate, or invalid records can undermine analytics and reporting. Automate validation and enforce critical business rules.
- Building tightly coupled pipelines: Dependencies between components make updates harder and increase the risk of cascading failures. Use modular components with clearly defined dependencies.
- Retrying jobs without safeguards: Uncontrolled retries can create duplicate records or inconsistent results. Implement idempotent writes, checkpoints, and safe recovery mechanisms.
- Overengineering the architecture: Unnecessary tools and complex processing patterns increase maintenance overhead. Choose technologies based on actual workload requirements.
- Neglecting monitoring: Failed jobs and stale datasets can go unnoticed without proper visibility. Monitor pipeline health, data freshness, and quality metrics.
- Granting excessive data access: Unnecessary permissions increase security and privacy risks. Apply least-privilege access and review permissions regularly.
- Skipping documentation and lineage: Missing documentation makes troubleshooting and impact analysis more difficult. Maintain dataset definitions, ownership details, and dependency information.
- Ignoring storage and compute costs: Inefficient queries and resource usage can increase costs as workloads grow. Review consumption, optimize queries, and apply storage lifecycle policies.
- Failing to test recovery procedures: Untested recovery processes can prolong production outages. Regularly test backfills, data restoration, and incident response procedures.
How to Prevent These Mistakes
Start with the problems that pose the greatest risk to your business. For critical pipelines, prioritize data correctness, secure access, reliable recovery, and monitoring before investing heavily in advanced optimization.
Review recurring incidents and operational costs regularly. Small improvements to existing workflows can often deliver more value than introducing additional tools or redesigning the entire platform.
The objective is not to eliminate every possible failure. It is to make failures detectable, recovery predictable, and data trustworthy.
How to Measure the Success of Data Engineering Best Practices
Implementing data engineering best practices is only part of the process. Teams also need measurable indicators to determine whether their pipelines are becoming more reliable, efficient, and useful to downstream consumers.
Choose metrics that reflect business requirements rather than tracking every available system metric. A pipeline supporting financial reporting may prioritize correctness and reconciliation, while a real-time application may place greater emphasis on latency and availability.
Key Metrics for Evaluating Data Pipelines
| Metric | What it measures | Why it matters |
| Pipeline success rate | Percentage of scheduled runs that complete successfully | Shows execution reliability |
| Data freshness | How recently a dataset was updated relative to its required update time | Indicates whether data is available when consumers need it |
| Processing latency | Time taken for data to move through the pipeline | Helps evaluate performance and responsiveness |
| Data quality failure rate | Frequency of failed validation checks | Reveals problems with completeness, validity, or consistency |
| Mean time to detect (MTTD) | Average time taken to detect an incident | Indicates how quickly monitoring identifies problems |
| Mean time to recover (MTTR) | Average time taken to restore service after an incident | Helps assess incident response and recovery effectiveness |
| Processing cost | Cost of running ingestion, transformation, and related workloads | Supports cost optimization |
| Resource utilization | How effectively compute, memory, and storage resources are used | Helps identify bottlenecks and overprovisioning |
| SLA/SLO attainment | Whether agreed service commitments and internal targets are met | Connects technical performance to business expectations |
How to Establish Useful Targets
- Identify critical datasets. Classify pipelines according to their business impact and downstream dependencies.
- Measure current performance. Establish a baseline for success rates, freshness, failures, and costs before setting improvement targets.
- Define realistic thresholds. Set targets based on consumer needs, technical constraints, and the consequences of missed commitments.
- Review trends over time. Evaluate whether reliability and efficiency improve across weeks or months rather than relying on isolated results.
- Connect metrics to action. Assign owners to investigate recurring failures, missed freshness targets, and unexpected cost increases.
Ready to Optimize Your Data Pipelines for Performance, Quality, and Scale?
Conclusion
Reliable data pipelines require more than the right tools. They depend on clear requirements, appropriate architecture, consistent data quality checks, safe processing, effective monitoring, and well-defined recovery procedures.
The 15 data engineering best practices outlined in this guide provide a practical foundation for building pipelines that scale while maintaining data quality, security, and operational reliability.
However, implementing every practice at once is rarely necessary. Start by identifying your biggest risks, such as unreliable ingestion, inconsistent transformations, limited monitoring, or rising infrastructure costs. Address those gaps first, then expand your controls as your data platform and business requirements evolve.
Review pipeline performance regularly, automate repetitive tasks, and ensure every dataset has clear ownership and measurable expectations. If you need expert support to build, optimize, or scale your data pipelines, partner with us for reliable data engineering services tailored to your business needs.
Ultimately, the goal is to build a data platform that delivers trustworthy information consistently, supports changing business needs, and remains manageable as data volumes and workloads grow.
Frequently Asked Questions
1. What are data engineering best practices?
Data engineering best practices are methods for designing, building, testing, securing, and maintaining reliable data pipelines. They include defining data requirements, automating quality checks, using incremental processing, managing dependencies, monitoring performance, and protecting sensitive information.
2. What makes a data pipeline reliable?
A reliable data pipeline processes data correctly and consistently, meets its freshness requirements, handles failures safely, and provides clear monitoring and recovery mechanisms. Idempotent processing, automated validation, checkpoints, and effective alerting all contribute to reliability.
3. How can data pipeline quality be improved?
Improve data pipeline quality by defining business rules, validating data at important processing stages, detecting schema changes, monitoring freshness, and investigating recurring failures. Automated tests help identify problems before unreliable data reaches downstream consumers.
4. What is the difference between ETL and ELT?
ETL stands for extract, transform, and load. Data is transformed before being loaded into the target system. ELT stands for extract, load, and transform. Data is loaded into the target platform first and transformed there, often using its processing capabilities. The appropriate approach depends on the architecture, workload, and governance requirements.
5. What tools are commonly used in data engineering?
Common tools include Apache Airflow, Dagster, and Prefect for orchestration; Airbyte and Debezium for ingestion and change data capture; Apache Spark and Apache Flink for data processing; dbt for analytical transformations; and platforms such as Snowflake, BigQuery, and Amazon Redshift for analytical storage. Tool selection depends on the workload and existing infrastructure.
6. How do data engineering teams reduce pipeline costs?
Teams reduce pipeline costs by processing only changed data when appropriate, optimizing queries, choosing suitable storage formats, managing compute resources, and applying data retention policies. Monitoring workload usage helps identify unnecessary processing and opportunities for improvement.
7. How does DataOps relate to data engineering best practices?
Data engineering best practices describe how to build and maintain reliable data systems. DataOps applies collaborative, automated, and continuous-improvement principles to the delivery and operation of data workflows. Practices such as version control, CI/CD, automated testing, monitoring, and incident reviews support both.
8. How can data engineering teams prevent duplicate records?
Teams can use stable business keys, idempotent writes, upsert operations, deduplication rules, and reliable checkpoints. The correct approach depends on the source system and the meaning of a duplicate. Pipelines should also account for retries, late-arriving records, and updates to existing data.
9. How often should data pipelines be monitored and reviewed?
Critical pipelines should have automated monitoring and alerts that operate continuously or according to their execution schedule. Teams should periodically review reliability, data quality, security, performance, and costs, with more frequent attention given to workloads with higher business impact.
10. How can data engineering best practices support AI applications?
They help ensure that AI applications receive accurate, current, well-documented, and appropriately governed data. For machine learning, this includes preventing data leakage and validating features. For retrieval-augmented generation, it includes maintaining document freshness, metadata, access controls, and reliable indexing. These practices improve data readiness but do not independently guarantee AI output quality.